I train real-time multimodal agents that talk, listen, and act while the interaction is still going. I build the tasks, synthetic data, and rewards, then train with RL.
At  Meta Superintelligence Labs I lead synthetic data for Muse Realtime Avatar, and developed offline RL for Vibes’ personalized feed. Before that, I worked on Visual Intelligence at
 Apple and foundation models at
 MIT-IBM Watson. I got my Ph.D. in Computer Science at
 MIT, and B.A. in Physics at
 UC Berkeley. Outside work I read, write, bike, and hike.
- Talk to me
- I'm at COLM 2026, Oct 6–9. I want to compare notes on two things: rewards for real-time agents, and how far a task definition alone can carry an RL environment. If that's your problem too, email me. I reply.
Research
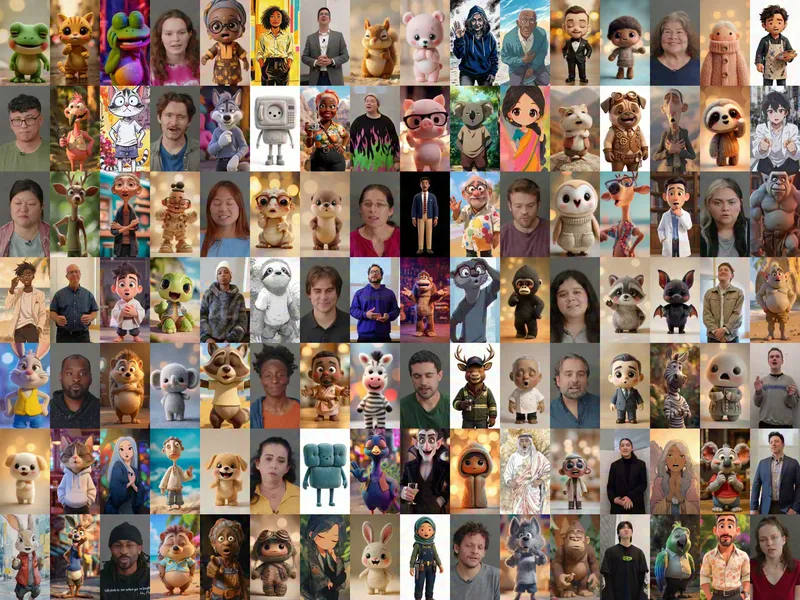
Muse Realtime Avatar · Meta Connect 2026
A live, expressive avatar that talks with you in real time. I lead its synthetic data, and applied self-forcing and DMD distillation to make it fast enough to run live.
BlogKeynote
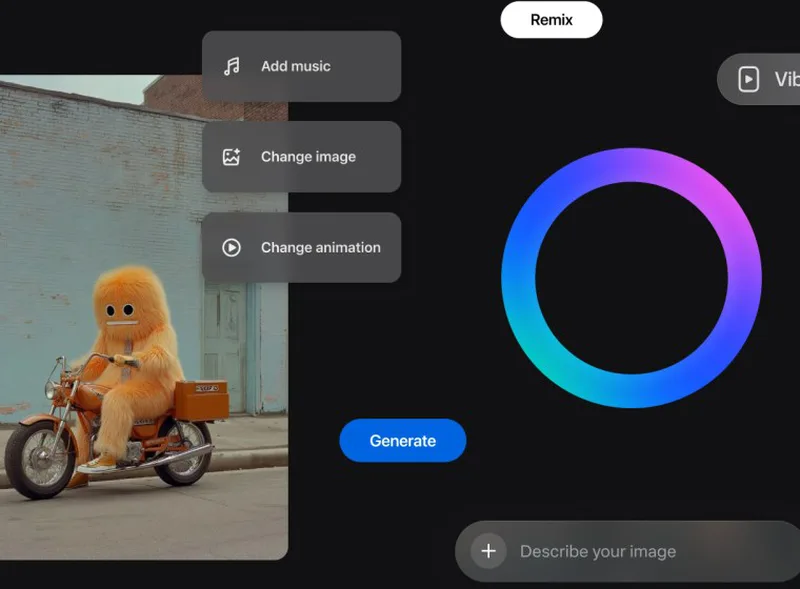
Vibes · 2025
Built the launch video-generation workflow, then developed preference learning and offline RL for Vibes, Meta AI's personalized video feed.
BlogEarnings callEurope
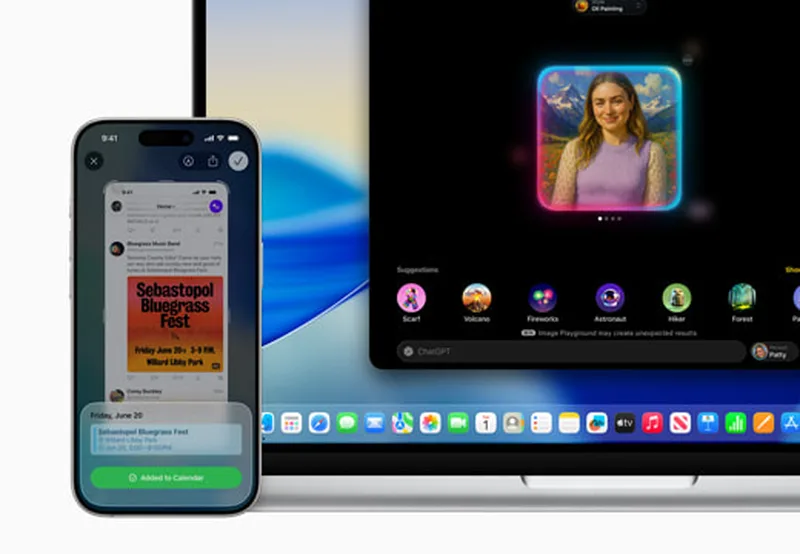
Apple · 2025
Built the datasets for on-device visual question answering on iPhone with privacy-preserving VLMs, and post-trained Apple's foundation model for Visual Intelligence. Shipped in Apple Intelligence at WWDC 2025.
BlogTech report
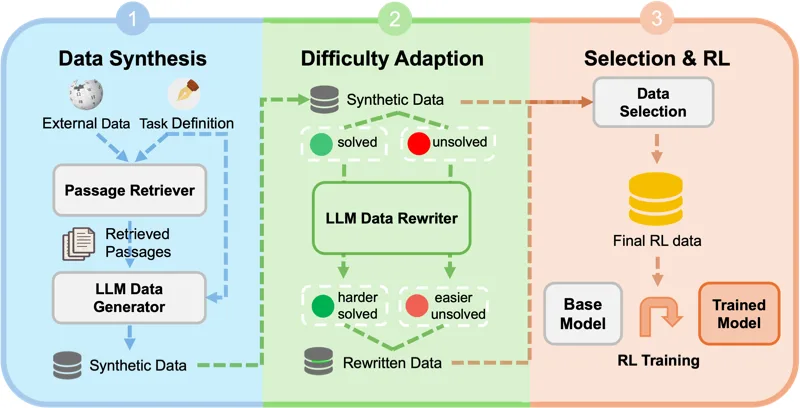
Synthetic Data RL · 2025
Given a target capability, synthesize the tasks, the environment, and the reward, then train with RL. No labeled dataset required; the task definition is the input.
PaperAPI Pack
JetMoE · 2024
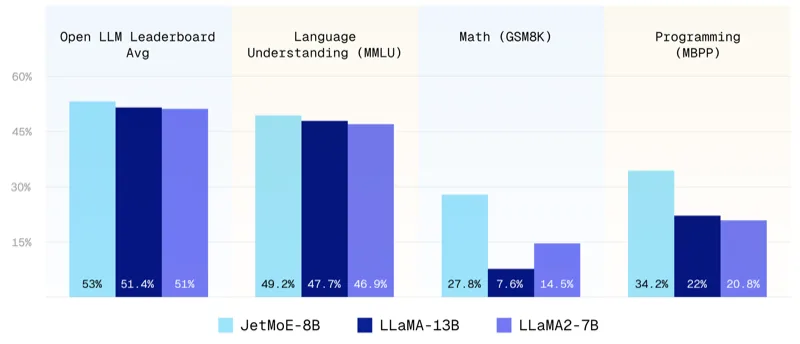
JetMoE-8B, an open-source mixture-of-experts model trained for a fraction of the usual cost, with a synthetic corpus for pre-training and post-training. Its chat model beats Llama2-13B-Chat on MT-Bench.
PaperCodeModelCSAIL
Octo-planner · 2024
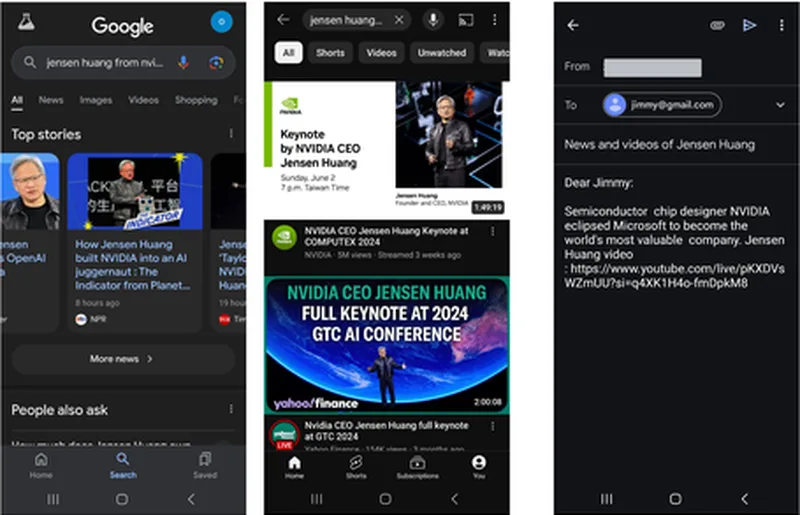
Efficient on-device task planning and decomposition, trained on a synthetic planning dataset with a multi-LoRA post-training pipeline.
PaperModelCSAIL
All publications → · Google Scholar →
News
-
Oct 2026 · Upcoming
At COLM 2026 in San Francisco, Oct 6–9. Email me to meet at the poster sessions or the Lifelong Agents workshop.
Read more →
-
Sep 2026
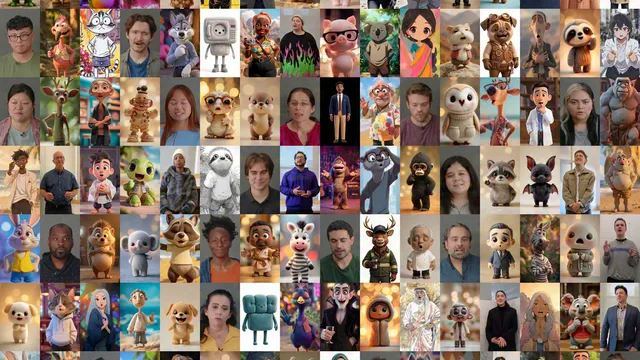
Muse Realtime Voice and Avatar announced at the Meta Connect 2026 keynote: one streaming system for conversation, speech, and a live, expressive avatar. I lead synthetic data for Muse Realtime Avatar.
Read more →
-
Jul 2026
Muse Spark 1.1 released, a multimodal reasoning model for agentic tasks, alongside the Meta Model API public preview.
Read more →
All news →
Essays on AI
- Sep 2026Real-Time Video Is a Control ProblemAI
A clip model never faces consequences. A real-time model does: any frame can change what the user does next. That makes it a policy, not a generator.
- Jul 2026Intelligence per Watt: Nobody Got Rich Owning the GridAI
When the headline metric becomes output per joule, a technology has become a utility. Intelligence just did, and the money will go where it always goes: upstairs.
- May 2026What Machines Can't StakeAI
Machines calculate. Humans commit. The gap is not intelligence — it is what you are willing to wager once the evidence runs out.
All essays →
